

Built for Generative AIat the Edge
The Challenge
Generative AI at the Edge Is a Memory Problem, Not a Compute Problem.
- Growing memory demands: A transformer’s attention cache grows with every token, putting pressure on a battery-powered device’s memory bandwidth.
- Separate processing blocks: Sensor pipelines require a DSP for filtering and an accelerator for the model—two blocks to license and verify.
- More compute isn’t enough: Adding TOPS solves neither the memory bottleneck nor the need for separate processing blocks.
 Growing memory demands: A transformer’s attention cache grows with every token, putting pressure on a battery-powered device’s memory bandwidth.
The Solution
Sequora Makes Memory a Constant, Not a Ceiling.
- Fixed-size state: Sequora is optimized for state space models (SSM) which hold history in a fixed-size state, so each token costs the same.
- One shared processing array: The same MAC array handles signal processing and neural processing, removing the separate DSP preprocessing stage.
- Predictable latency: Work is scheduled ahead of time, making latency deterministic.
 Fixed-size state:
Key Features
-
ISA-Based Architecture
Programmable like a CPU, efficient like fixed-function silicon — new algorithms ship as software.
-
Unified MAC Array
FFT- and MFCC-equivalent analysis runs on the same array as the neural layers — no DSP preprocessing stage.
-
Native State-Space Processing
SSM / R-TENNs layers hold history in a fixed-size state, so memory is constant for any signal length.
-
Built for Time Series
Audio, vibration, EEG and radar at constant compute per sample, with no frame buffering.
-
Memory-Efficient Generative Decode
Patented non-linear 4-bit codes use 4x less memory. SSM decode cuts per-token memory traffic to a level an edge platform can utilize.
-
Frozen Frequency Layers
Physics-specified values that need no retraining, so the deployed model stays certifiable.


Licensed as RTL,Integrated on Your Node
Sequora is delivered as process-portable, fully synthesizable RTL with verification IP, alongside the software and documentation your team needs to bring it up. You integrate it on your own node, on your own schedule, in your own flow. The product brief has the full deliverables list.
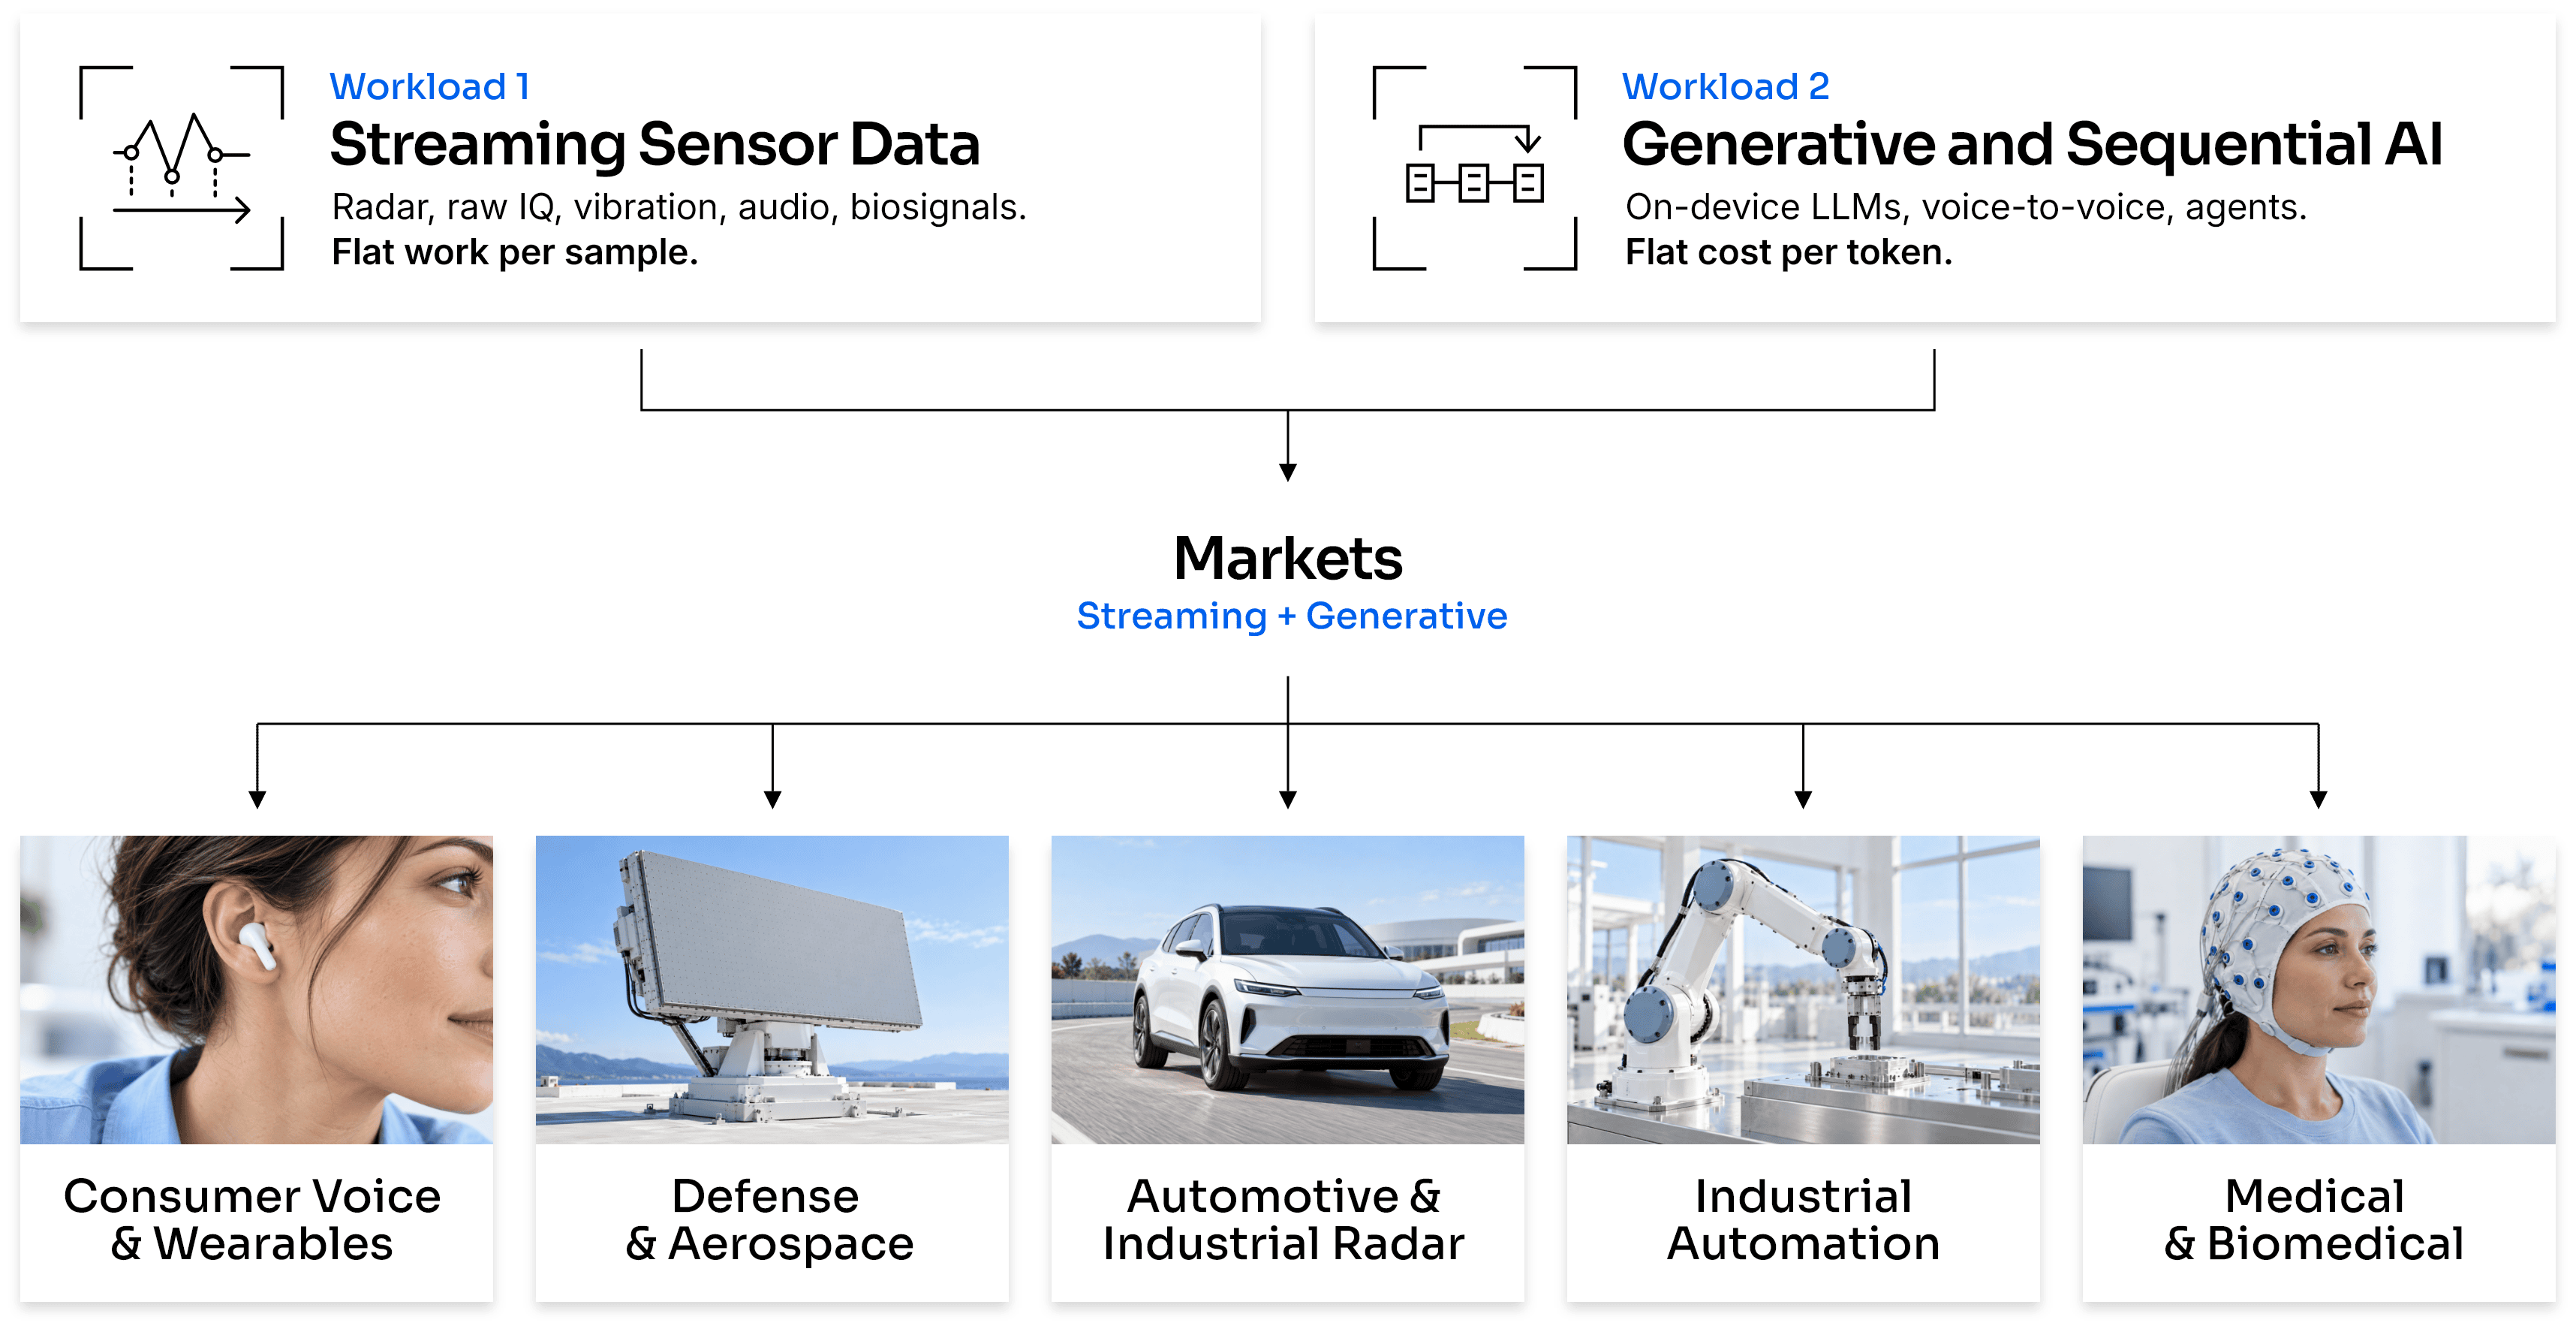
Where Sequora Deliversthe Most Value
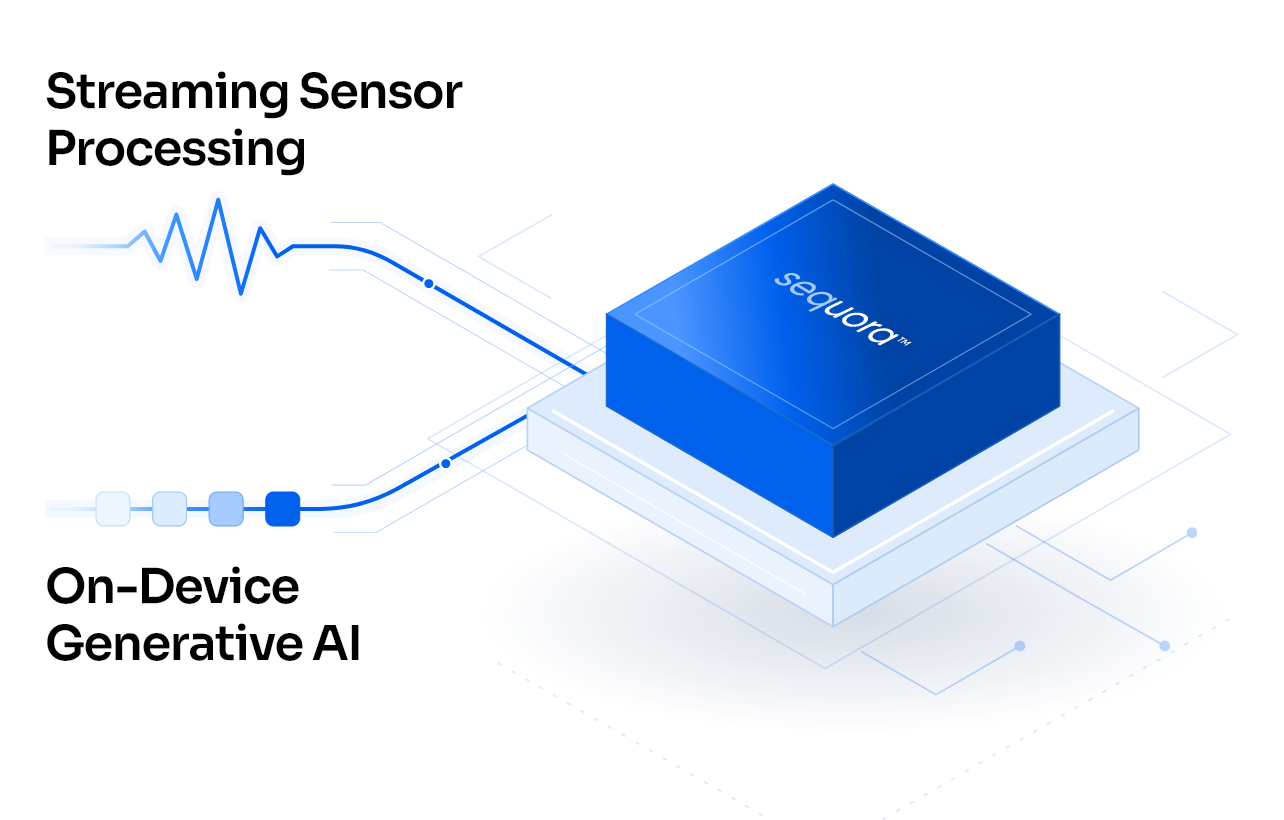
Sequora supports both continuous sensor processing
and generative inference on the same core.
Tell Us What You
Are Building
We will set up a technical briefing with the people who built it.
If you want the datasheet, ask here and we will send it.
Sequora is available now for licensing evaluation.
Performance characteristics are preliminary and subject to change.